05Research Assistant, University of Alberta · Jun–Aug 2026
Q-Learning Grid World
8steps in the shortest path, which the agent learned · the minimum possible on this grid
Training log
- Exit found in 9 steps!
- Exit found in 8 steps!
- Exit found in 9 steps!
- Exit found in 10 steps!
- Exit found in 10 steps!
- Exit found in 8 steps!
- Exit found in 9 steps!
- Exit found in 8 steps!
- Exit found in 10 steps!
- Exit found in 9 steps!
- Exit found in 10 steps!
- Exit found in 10 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 10 steps!
- Exit found in 8 steps!
- Exit found in 10 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 10 steps!
- Exit found in 9 steps!
- Exit found in 9 steps!
- Exit found in 8 steps!
- Exit found in 9 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 10 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 11 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 11 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 8 steps!
- Exit found in 9 steps!
- Training Completed.
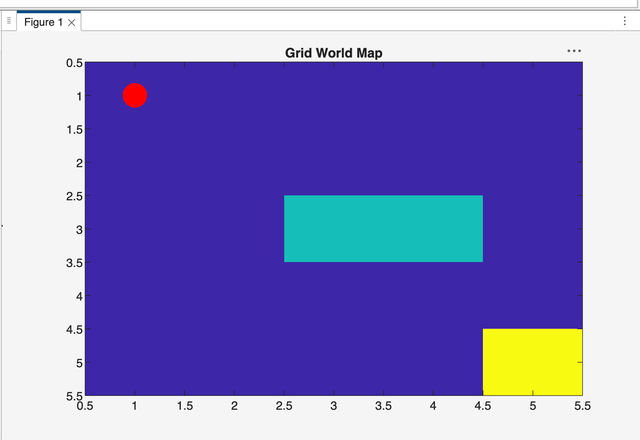
Illustration
Learned route: 8 steps.
Screenshot
What I implemented
As a research assistant in reinforcement learning at the University of Alberta, I implemented a grid world in MATLAB, with Q-learning written from scratch.
The environment is a 5×5 grid: start (1,1), goal (5,5), obstacles at (3,3) and (3,4). The rewards are +100 for the goal, −10 for a wall or edge, and −1 for each step.
I implemented epsilon-greedy action selection, a Q-table and Bellman updates.
I tuned the learning rate, the discount factor and the exploration rate to improve how quickly and reliably training converged.
I fixed a bug where the agent repeated the same move in untrained states, by adding random tie-breaking.
How I verified it
Over 500 episodes of training, the agent learned the shortest path: 8 steps, the minimum possible on this grid.
The training log on this page is MATLAB's own output for the last episodes. Individual training episodes still vary, between 8 and 11 steps.
I analyzed the learned Q-table to evaluate and improve the agent.
Reporting
I wrote weekly reports to the supervising professor, and a technical report.